Skip to content
Kartikey Agrawal

I build products end to end, from the database to the last button, and I do research on how small AI models reason. Second-year Data Science at BMSCE, originally from Kota.

Right now: getting HostelMate ready for its first college.

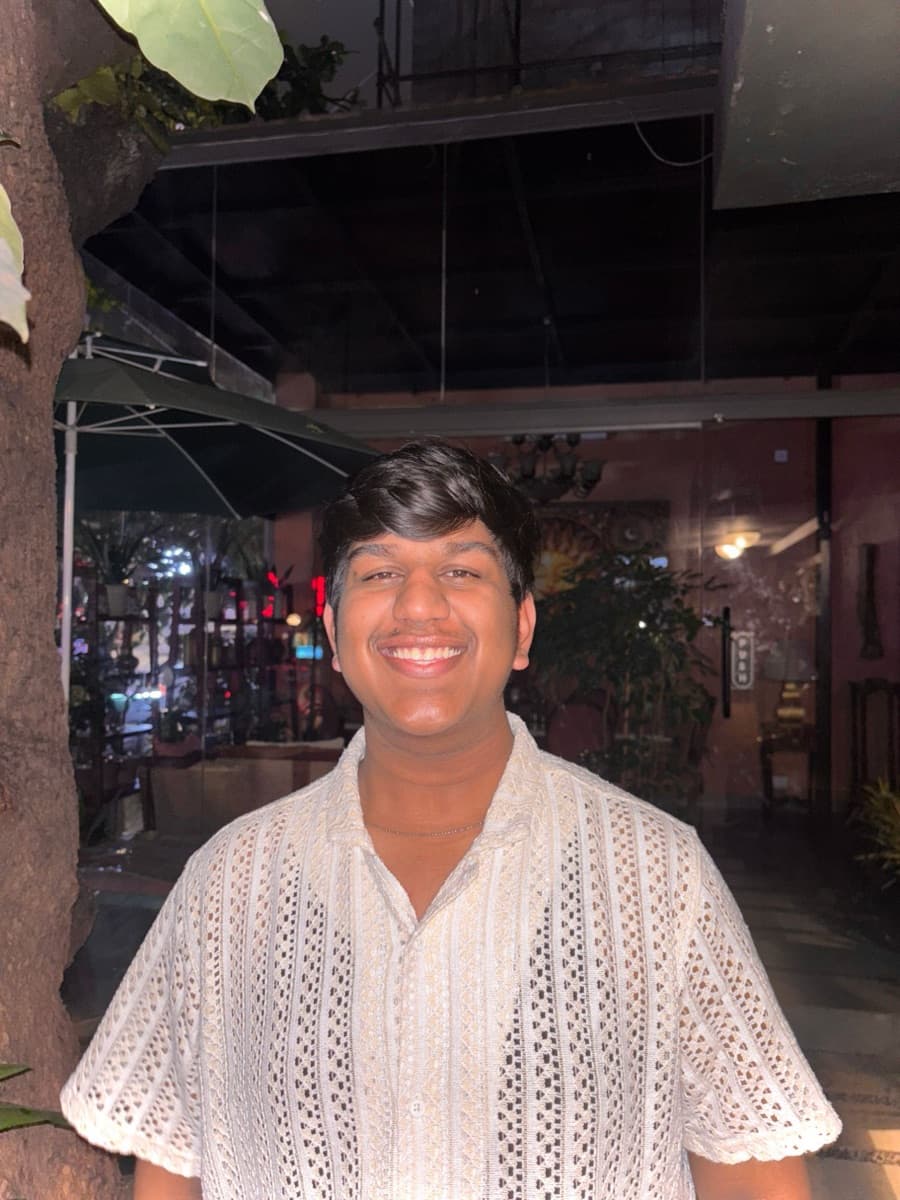
Kartikey smiling, in a white crochet shirt, at night outside a café
Kota → Bengaluru

Products Built and shipped

  1. HostelMate

    Live demo online (still being polished); preparing for its first college

    Indian college hostels still run on paper registers, WhatsApp complaint groups and handwritten leave forms.

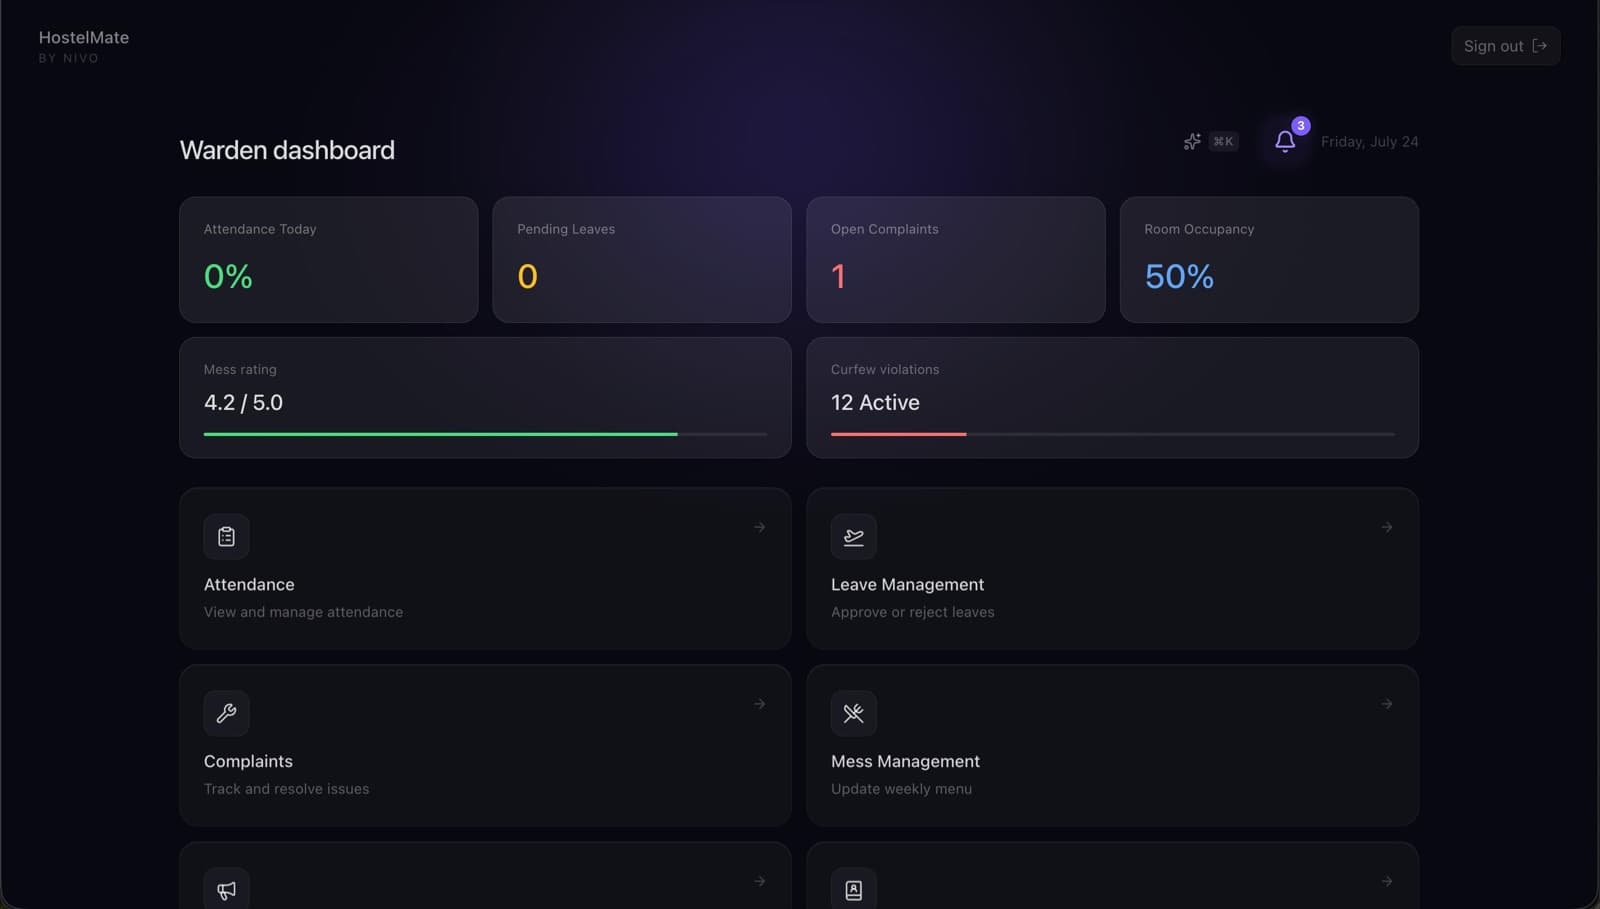
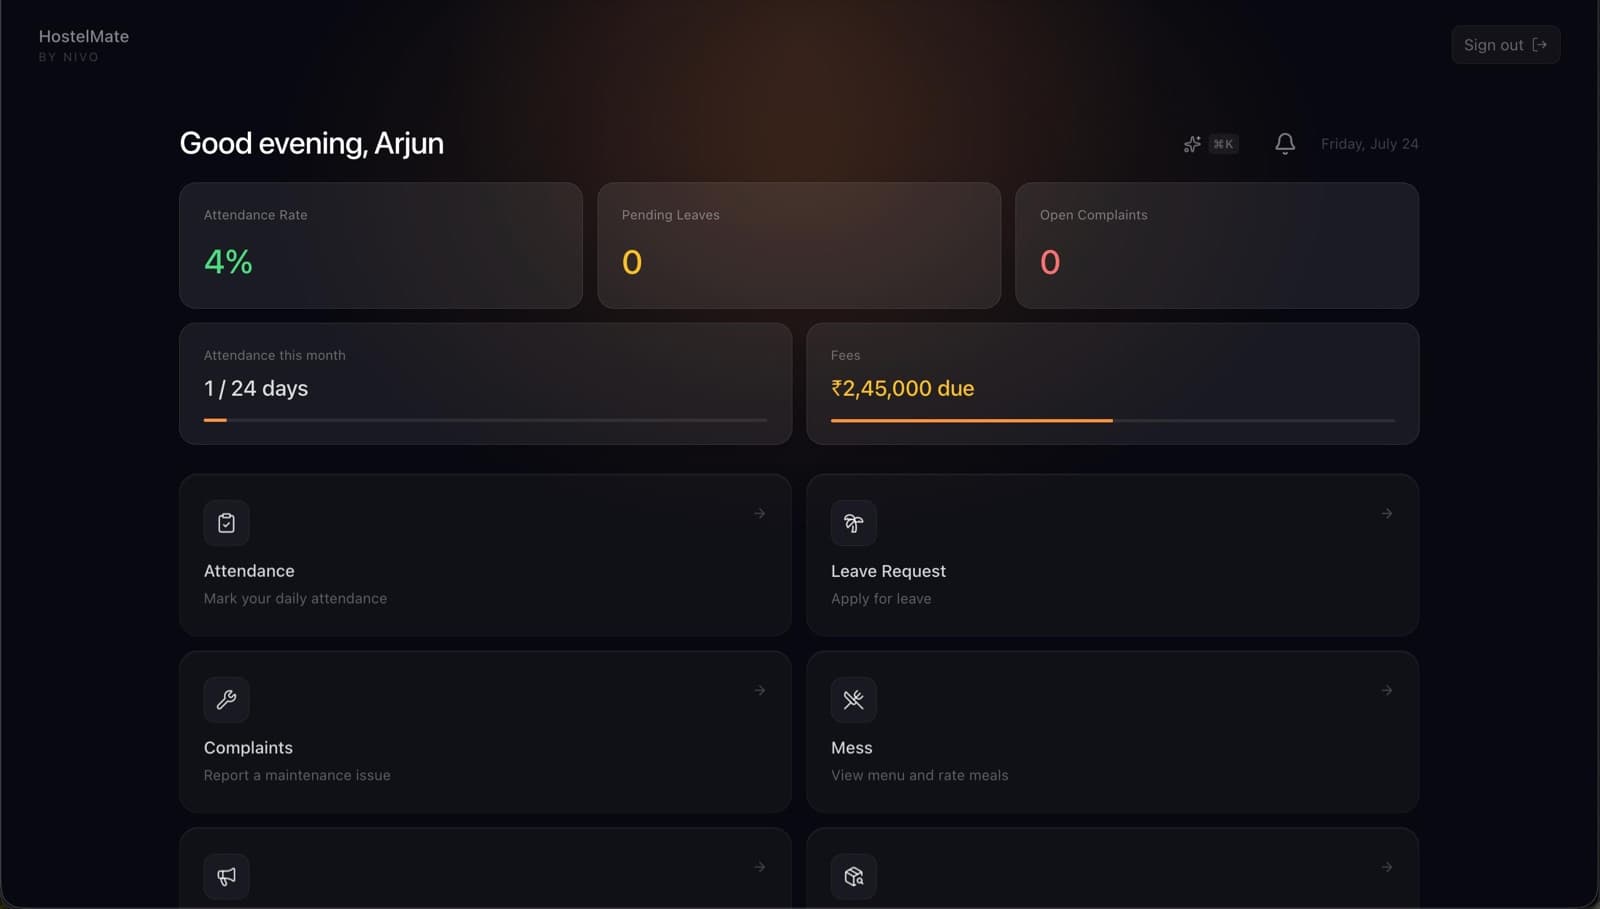
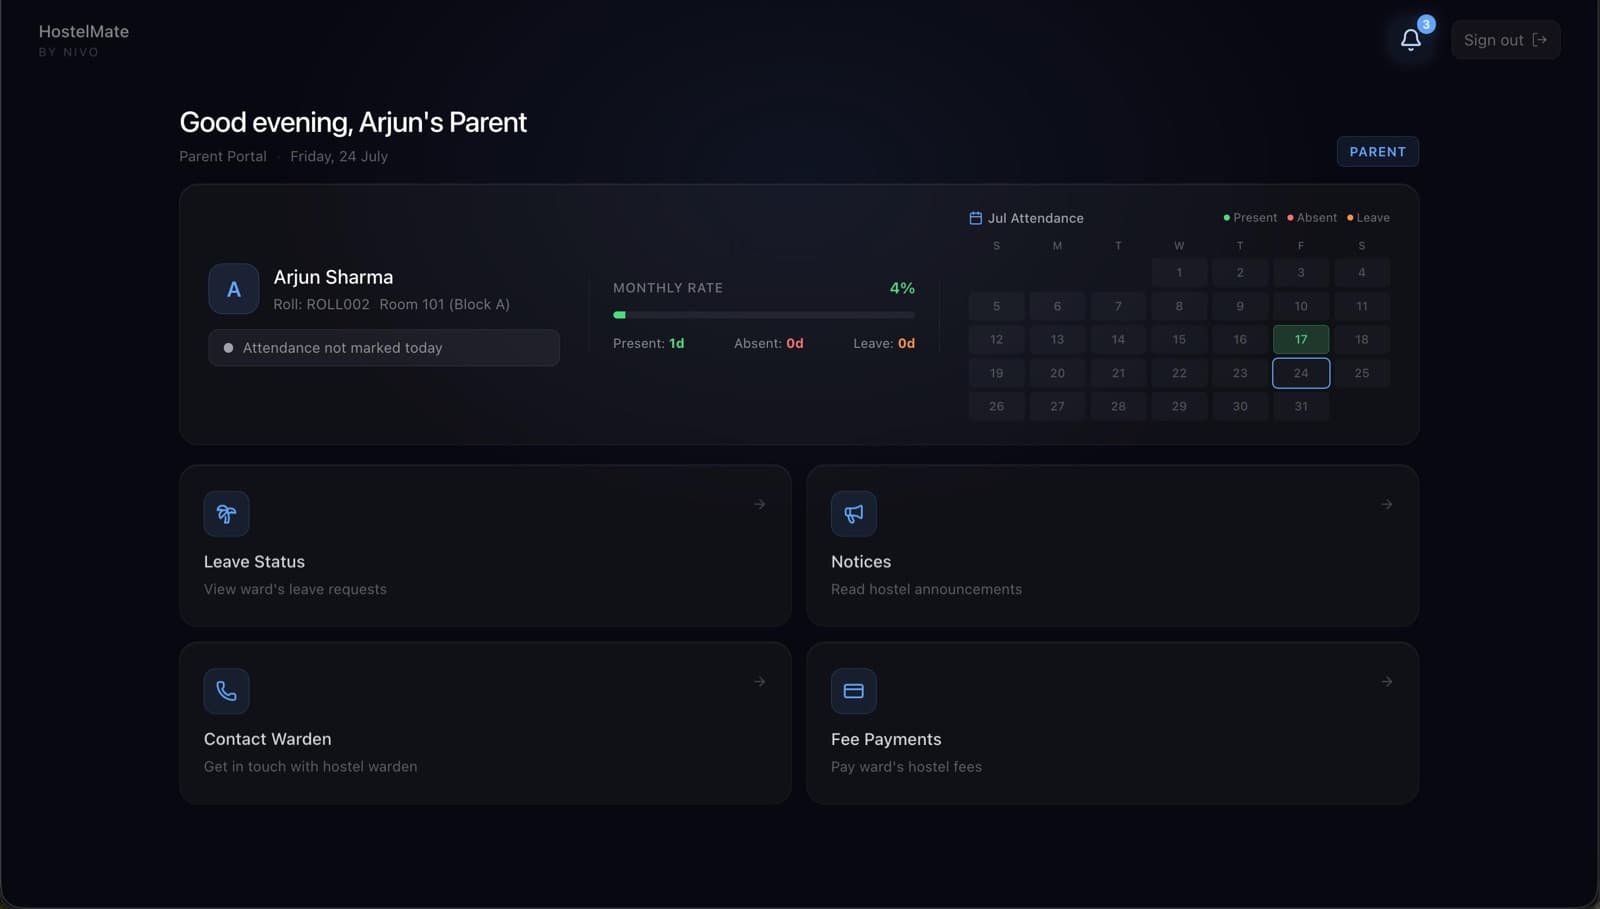
    One platform for students, wardens and parents: attendance, leave, complaints, mess, fees, visitors and lost-and-found.

    • Attendance you can't mark for a friend: a rotating HMAC-signed QR code, checked together with a 100 m GPS fence.
    • Face check in the browser (blink, motion, five angles), so verifying a student costs nothing per scan.
    • Complaints triaged by an LLM (Llama 3.1 on Groq): category, urgency and a summary for the warden; a 30-day view spots recurring problems.
    • Fees paid online through Razorpay, every payment's signature verified; visitors go through warden approval.
    • Live notifications over Redis and Socket.io instead of polling.
    • 260+ Jest tests in 23 suites and 59 Playwright end-to-end tests, run by a pre-commit hook and CI; an 80% line-coverage floor.

    Sole engineer (1,124 commits), 2026 – nowNext.js, Express, Supabase (PostgreSQL), Redis, Socket.io, Groq, Razorpay, Docker, TurborepoLive demoSourceDocs

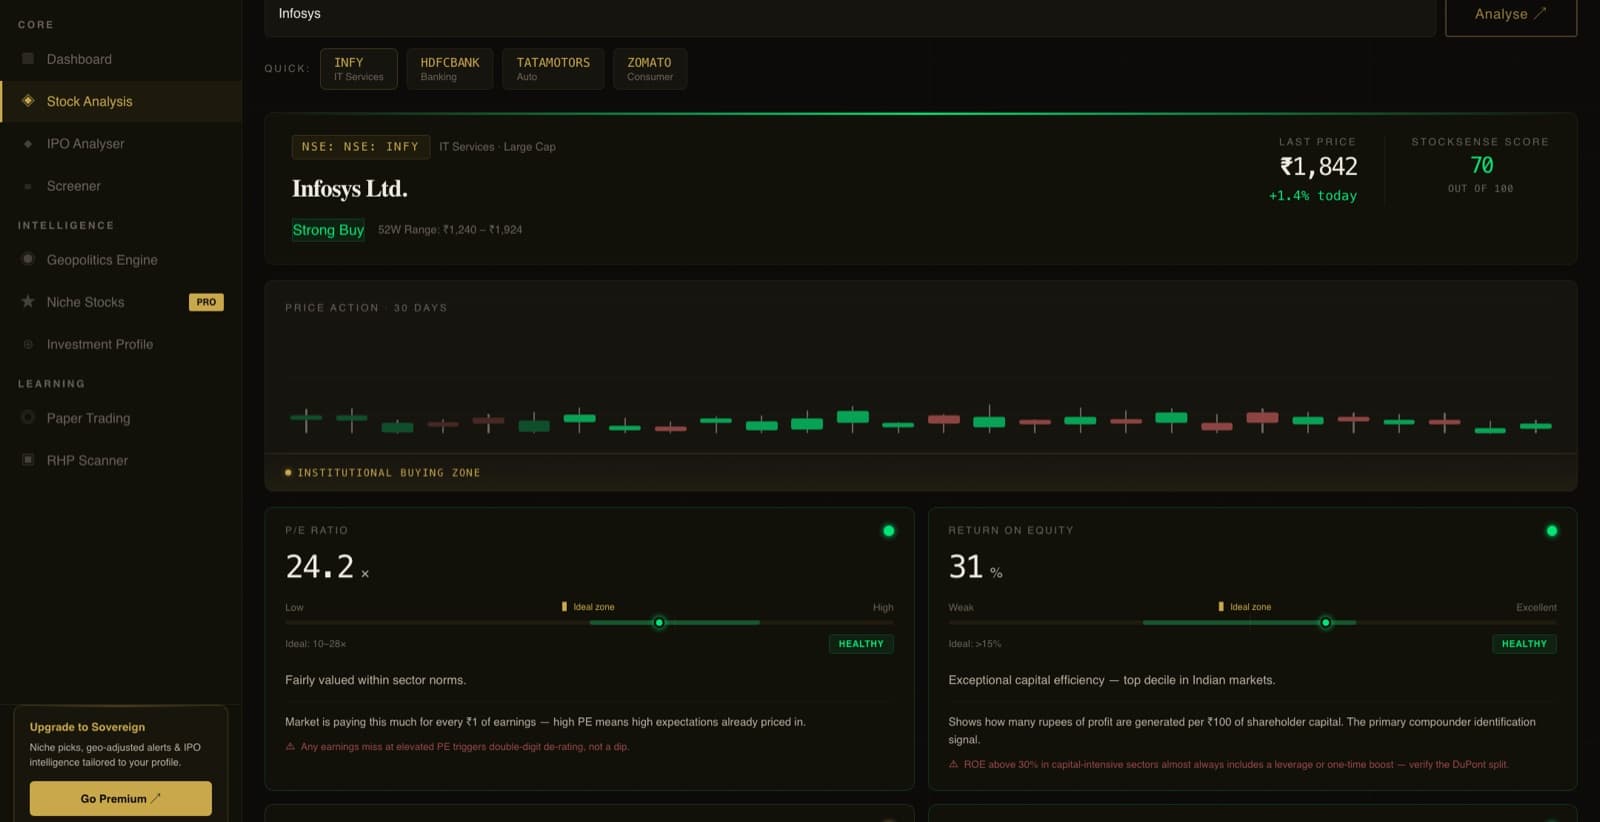
  2. StockSense

    In development

    Retail investors in India see a P/E of 24 and can't tell if that's healthy, because what's normal differs by sector.

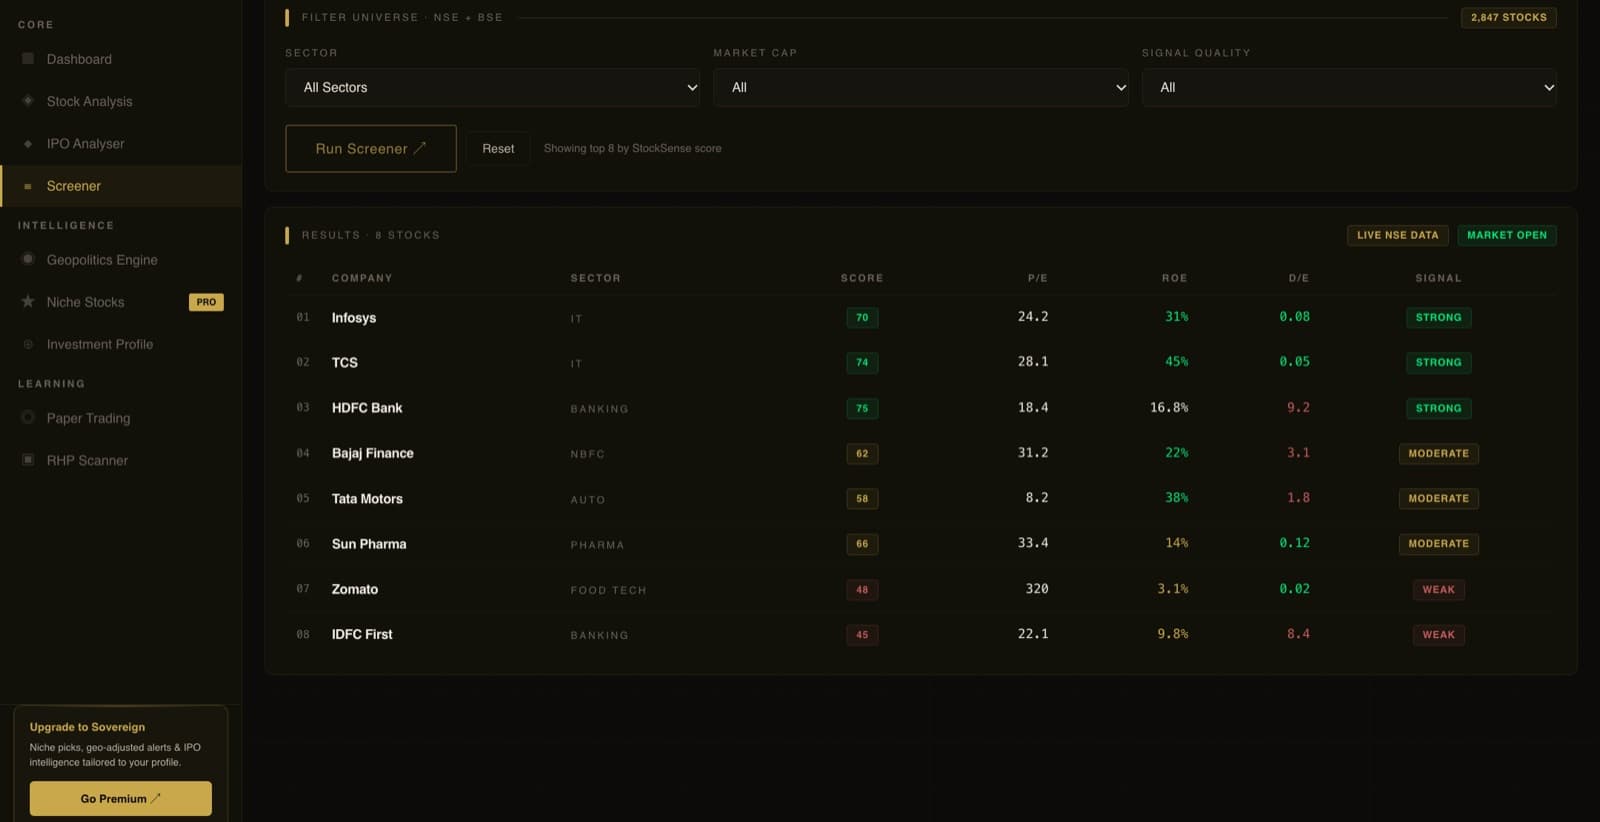
    Stock research that scores every NSE company on six fundamentals against its own sector, and explains each score in plain language.

    • Live prices for 2,200+ NSE stocks, with no API calls while the market is closed.
    • Reads 400-page IPO prospectuses and pulls out the risks in under 30 seconds.
    • Screener, IPO scoring, a geopolitical risk map and paper trading.

    Built the product, data pipeline and interface, 2026 – nowNext.js, Python, FastAPI, Supabase, pgvector, FinBERTSource

  3. FoodBridge

    Finished

    Restaurants throw away good food while NGOs nearby run short.

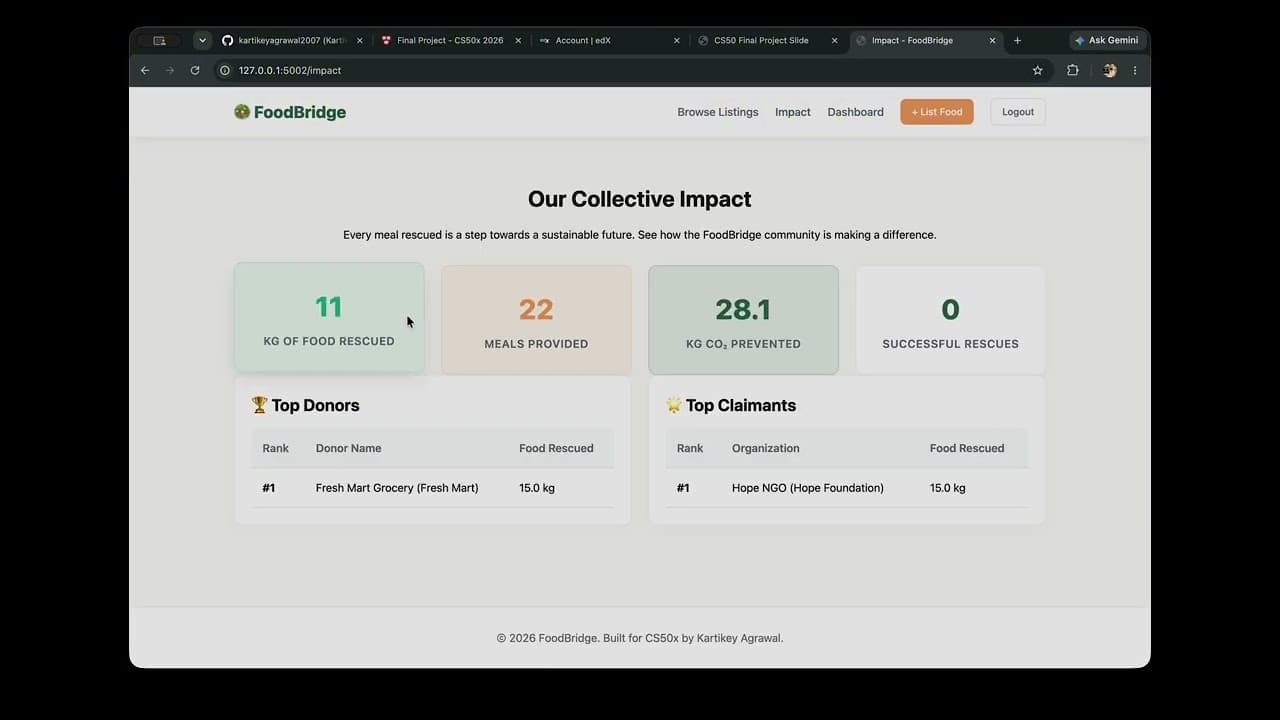
    A marketplace where donors list surplus food and NGOs or volunteers claim it before it expires.

    • Live countdowns and urgency colours on every listing.
    • Claims are atomic, so two NGOs can never take the same food.
    • Tracks food rescued, meals provided and CO₂ prevented.

    Solo, Harvard CS50x final project, 2026Python, Flask, SQLiteWatch the demoSource

Research district Papers, benchmarks and tools

  1. Do small models talk themselves out of right answers?

    Accepted at ICTCS 2026, presenting mid-December

    A common test truncates a model's reasoning and forces an answer. If an early forced answer is right and the final one wrong, people call it 'overthinking'. But forcing the answer is itself an intervention.

    A two-tier protocol that separates what the probe forces from what the model actually commits to, run on DeepSeek-R1-Distill-Qwen-1.5B, Qwen2.5-3B and Llama-3.2-3B over GSM8K and MATH-500.

    • 210 uninterrupted traces; 11 flagged as degradation (5.2%).
    • Two annotators, the second blind, agreed on all 11 (Cohen's κ = 1.00).
    • Only 1 of the 11 is genuine: the probe measures itself as much as the model.

    Co-author, with Mayanka Gupta, Kiran A Gupta, Utkarsh Mandal, Abhigyan Shekhar and Parth Bhat, 2026PyTorch, Hugging Face, GSM8K, MATH-500

    11 of 210 traces looked like a model abandoning a right answer.

    • 6 never declared an answer before the token budget ran out
    • 3 were wrong without ever declaring a correct answer first
    • 1 was still correct once the probe was removed
    • 1 genuinely gave up a correct answer for a wrong one
    Each square is one flagged trace, checked by two annotators.
  2. Gearbox

    Almost complete, paper in progress

    Expensive AI agents spend most of their tokens on small, routine subtasks a cheaper model could do, if anyone could trust the cheaper model's 'done'.

    An automatic transmission for AI agents: the agent hands subtasks to cheaper models, keeps working, and accepts an answer only after it passes a real test. Failures move up to a stronger model with exactly what failed.

    • Cheap-first with checking: 95.7% on HumanEval+, against 92.7% for always using the 27B model, at about a third of the compute.
    • The expensive model wrote about half as many tokens.
    • Tested on 542 problems and 12 open models on a lab GPU; our grader matches published scores within about 1 point.
    • Plugs into Claude Code, Cursor and Antigravity as an MCP tool.

    Built the tool and ran the benchmarks, 2026Python, LiteLLM, MCP, OllamaSource

    Accuracy on HumanEval+

    Always use the 27B model
    92.7%
    Cheap first, check, move up on failure
    95.7%

    Compute cost (relative, lower is better)

    Always use the 27B model
    27
    Cheap first, check, move up on failure
    8–9
    Gearbox benchmark, 164 problems with hidden tests, open models on one lab GPU.
  3. Punarvaani (पुनर्वाणी)

    Code complete and tested on CPU; GPU training next

    People who lose their voice to throat or oral cancer surgery, a stroke or ALS can still move their lips, but no sound comes out. India has one of the highest rates of oral and throat cancer.

    Reads a person's silent lip movements through a phone camera and speaks for them in Hindi, in their own voice rebuilt from old voice notes and videos: lips to text (an LLM fixes look-alike sounds) to cloned speech, or lips straight to speech units.

    • Every stage is written and tested on CPU (80+ tests): lip crop, a Hindi audio-video data engine, an AV-HuBERT encoder with LoRA, both speech paths, voice rebuilding, real-time streaming and evaluation.
    • On a synthetic lip-reading world, per-user personalisation cut the character error rate from 92% to 15.5% with 64 clips.
    • Next: mine Hindi video, record volunteers mouthing silently, and train on GPUs.

    Built the codebase, 2026 – nowPython, PyTorch, AV-HuBERT, LoRA, MediaPipe, IndicF5Source

  4. MetaGuard

    In progress

    AI tutors can help so much that people stop learning.

    Psychology × AI research on how people learn with AI tutors.

    • Details after the study is published.

    Researcher, 2026 – nowLearning science, LLMs

  5. Amazon ML Challenge: one company, many spellings

    Top 5%

    Match the same business across three messy sources with about 12.5 million records: typos, swapped legal forms, missing addresses, and names written in Devanagari, Tamil, Telugu or Gurmukhi.

    A three-stage pipeline: cheap candidate search on rare name and address keys, a LightGBM matcher with about 70 features, and a decision layer that enforces one-to-one matches.

    • A transliteration dictionary learned only from the training pairs, so Indic-script names meet their English versions.
    • Score 0.965 out of 1, rank about 1,800 out of 35,000 teams.

    Team DayTrippers, four members, Sep 2026Python, LightGBM, rapidfuzz, sparse_dot_topn

    विजन प्रोडक्ट्स प्राइवेट लिमिटेड=Vision Products Private Limited
    1. Find candidates on rare name and address keys
    2. Score each pair with about 70 features
    3. Keep one match per record
    A real pair from the training data: the same company, two scripts.

Market street Smaller builds

AI Meeting Intelligence

Action items get lost after meetings.

Turns meeting audio into action items, decisions and open questions, each linked to the exact quote and speaker.

David: Work on the actual working design of the remote control, due next meeting

“as the industrial designer, you're going to be working on the actual working design of it”

Word error rate (lower is better)

Whisper Large-v3
40%
This pipeline
6.67%
From a recap of a public AMI corpus meeting. Error rates on the same multi-speaker audio.

Solo, 2026Python, FastAPI, AssemblyAI, GroqSource

AI hiring assistant

Hiring managers drown in candidate PDFs.

Reads résumés, normalises skills and recommends matches. The final score is plain code, so the AI can't be talked into a result.

Every AI output is validated against a schema before it's saved.

Solo, technical task for Zelosify, Sep 2026Next.js, Express, Prisma, GeminiSource

AshCam

A playful one: leaving a video call is dull. What if you could vanish the way the Endgame snap does it?

A macOS virtual camera: snap your fingers and you turn to dust while the room behind you stays live; snap again to come back. Works in WhatsApp, FaceTime, Google Meet and Zoom through OBS.

A snap counts only when the camera sees the thumb and middle finger snap apart and the mic hears the click, so claps and typing don't set it off.

Solo, Oct 2026Python, OpenCV, MediaPipe, ONNX Runtime, pyvirtualcamSource

Under construction Ideas I’m still building

Mandi bot

My father trades grain at Bhamashah Mandi in Kota and checks prices on a website every morning.

A bot that fetches today's prices for what he holds and predicts profit from incoming crop arrivals and the weather.

BMSCE events bot

Our college runs events all the time, and the tech ones get lost in WhatsApp groups.

A bot that reads the groups and tells me only about hackathons and tech events.

About And the training ground

B.E. Computer Science (Data Science) at BMS College of Engineering, 2024 – 2028. CGPA 8.42.

Work

  • Software developer intern, Trinkerr Jun – Aug 2026
    Investment poll platform in Django and React
  • Social media manager and web dev intern, Veynqor Apr – May 2026
    Remote, US-based B2B startup; built its website

Right now

  • Getting HostelMate ready for its first college
  • Finishing Gearbox and its paper
  • Presenting our ICTCS paper in mid-December

Training ground

CodeforcesSpecialist
1443
DSAproblems in C++ (Striver A2Z, Love Babbar)
200+
Harvard CS50xcertificate, weeks 0–9 in C
✓
AbacusUCMAS All-Rajasthan Championship, 2015
1st

Open to SWE or ML internships

Say hello